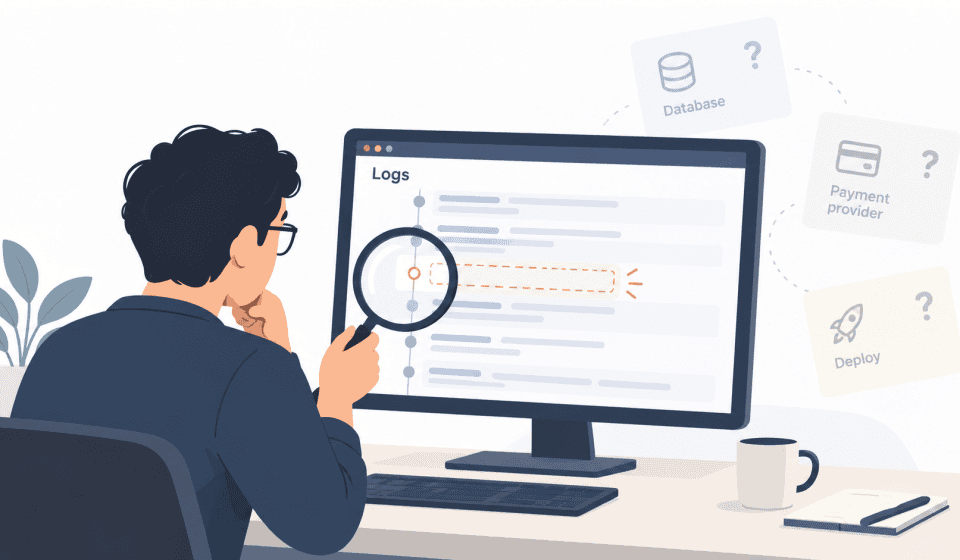

A production bug appears. Payments are failing, users are reporting issues, and the team starts looking for answers.
Someone says, “It looks like a database issue.” Another person thinks the payment provider may be having problems. Someone else suggests rolling back the latest deployment.
Within a few minutes, there are already several theories on the table. The problem is that there is still very little evidence.
This is where one of Sherlock Holmes’s most famous observations becomes surprisingly relevant to software engineering:
“It is a capital mistake to theorize before one has data.”
Holmes was talking about investigation, but the same principle applies almost perfectly to debugging. When we decide too early what the problem is, we often stop investigating objectively. Instead of using facts to test a theory, we start looking for facts that support the theory we already have.
That is how debugging slowly turns into guessing.
When Debugging Becomes Guessing
The pattern is very common.
A bug report arrives. You inspect the code and notice something that looks suspicious. You change it, the tests pass, and the fix is deployed.
A few hours later, the same problem happens again.
So another part of the code is changed. Then another.
Each individual change may look reasonable, but without enough evidence, we are effectively experimenting with the system until something happens to work.
A better debugging process starts with questions rather than solutions.
For a payment failure, for example, I would first want to know whether the request actually reached our server. Is the problem affecting every user or only a specific group? Did we send the request to the payment provider? What response did the provider return? Did the database transaction complete successfully? Did the problem start immediately after a recent deployment?
Once those questions have answers, many possible causes disappear automatically.
Instead of having ten theories, we may suddenly have two.
That is the real value of evidence in debugging. It reduces the search space.
Sometimes the Most Important Clue Is What Did Not Happen
There is another interesting lesson from Sherlock Holmes that is particularly useful when debugging distributed systems.
Holmes did not only pay attention to what happened. He also paid attention to what should have happened but did not.
In Silver Blaze, a horse disappears during the night. One of the important clues is that the guard dog did not bark. That absence of a reaction mattered because a stranger entering the area should normally have caused the dog to react.
Software systems often leave similar clues.
Suppose a payment request was sent successfully, but the expected webhook never arrived.
A database transaction started, but there is no committed log afterward.
A job was pushed to the queue, but there is no log showing that a worker ever picked it up.
An API request entered one service, but there is no trace of the downstream service receiving it.
When debugging, we naturally search for error messages and exceptions. Those are useful, but sometimes the strongest clue is simply the absence of something that should have happened.
A useful debugging question is therefore not only:
“What happened?”
It is also:
“What was supposed to happen next, and why didn’t it?”
That question can be especially powerful in systems involving queues, webhooks, background workers, external APIs, database transactions, or multiple services.
Mitigation and Root Cause Analysis Are Different Problems
Of course, production incidents are not detective stories. If customers cannot make payments, the team cannot spend hours investigating while the system remains broken.
The first priority is usually to reduce the impact.
If the issue started immediately after a deployment and rolling back is safe, rollback may be the most sensible first action. Restoring the service is often more important than understanding the exact cause in that moment.
But mitigation and root cause analysis are not the same thing.
If rolling back a deployment makes the problem disappear, we have learned something useful: some part of the recent change was related to the incident.
We still do not necessarily know which part.
Maybe a new query caused database contention. Maybe a configuration changed. Maybe an API payload changed. Maybe a background job started behaving differently under production traffic.
Rollback can restore stability, but it does not automatically explain the failure.
That investigation still needs to happen.
Fixing the Symptom Is Not Always Fixing the Problem
Another common debugging mistake is treating the symptom instead of the cause.
Imagine a service starts timing out after five seconds. One quick solution is to increase the timeout to thirty seconds.
The errors disappear.
Technically, the incident may look fixed.
But the most important question remains unanswered:
Why did the service become slow in the first place?
Maybe a database query lost an index. Maybe an external API became slower. Maybe a new feature introduced an N+1 query problem. Maybe a queue that normally handles expensive processing asynchronously is no longer working.
Increasing the timeout might be a perfectly reasonable temporary mitigation, but if we stop there, the real problem remains inside the system.
Eventually it may return in a different form.
A More Reliable Debugging Process
For me, a practical debugging process looks something like this:
- Reduce the impact first.
Restore service when possible through rollback, feature flags, traffic controls, or another safe mitigation. - Collect facts.
Check logs, metrics, traces, database state, external provider responses, and the scope of the failure. - Build a hypothesis.
Use the evidence to identify a plausible explanation. - Test the hypothesis.
Try to prove or disprove it using reproducible behavior, logs, data, or controlled experiments. - Discard wrong theories quickly.
A failed hypothesis is useful because it removes one possibility from the investigation. - Fix the root cause.
Once the cause is understood, make the smallest reliable change that addresses it.
The actual code change may eventually be only two lines.
Finding the correct two lines is usually the difficult part.
Good debugging is therefore not mainly about how quickly we can modify code. It is about how efficiently we can move from uncertainty to evidence, from evidence to a hypothesis, and from a hypothesis to a verified cause.
The next time something breaks in production, perhaps the first question should not be:
“What should I change to fix this?”
A better starting point might be:
“What do I actually know so far, and what was supposed to happen but didn’t?”
That small change in mindset can turn debugging from a guessing game into an investigation.